After 600 experiments, here's what I discovered about JEPA world models
Six hundred experiments on the LeWM world model show hierarchical planning through 25-step subgoals boosts long-horizon task success from 22% to 85%.
By Dillip Chowdary • Nov 14, 2026 • Source: haddyalchaer.com
Independent machine learning researcher Haddy Alchaer published findings from six hundred controlled experiments examining the joint-embedding predictive architecture world model known as LeWM, detailed in haddyalchaer.com's report. The research evaluated how the architecture, released this year by a team including Yann LeCun, performs on the standard Push-T robotics simulation. Alchaer demonstrated that algorithmic planning adjustments can raise task completion rates from 22 percent to 85 percent without retraining the underlying neural network.
This technical analysis covers how latent embeddings, memory graphs, and goal transformations reshape long-horizon robotic manipulation tasks. It is designed for robotics engineers, reinforcement learning researchers, and system architects building autonomous decision systems. Readers will examine the precise mechanisms that eliminate compounding prediction errors during complex multi-step trajectory planning.
01Predictive accuracy across simulated physics benchmarks
The Joint-Embedding Predictive Architecture splits world modeling into an encoder, a predictor, and an action planner. The encoder compresses observation frames into compact vectors, while the predictor forecasts next-step embeddings given candidate actions. In Push-T, a blue robot pusher maneuvers a gray T-shaped block toward a green target painted on a table surface.
To determine whether predictive errors constrain LeWM, the researcher replaced the learned predictor with the simulator's exact physics engine across two hundred fifty tasks. Given expert subgoals every twenty-five steps, vanilla LeWM achieved a 78 percent success rate, while true physics scored 77 percent. The learned representation already matches ground-truth simulation when evaluated along familiar training trajectories.
Because the learned predictor matches perfect physics along nominal paths, model accuracy is not the primary bottleneck in long-horizon performance. Future capabilities depend on how autonomous systems organize and execute sequential plans rather than training larger predictors. The discovery redirected experimental focus toward multi-step search procedures within latent vector spaces.
02Hierarchical planning over twenty-five step horizons
When tasked with reaching goals seventy-five steps away in a single search, vanilla LeWM achieved a 22 percent success rate. Supplying the simulator's exact physics for the full trajectory raised performance to 42 percent. Dividing the identical seventy-five-step horizon into three twenty-five-step segments boosted success to 80 percent without altering weights.
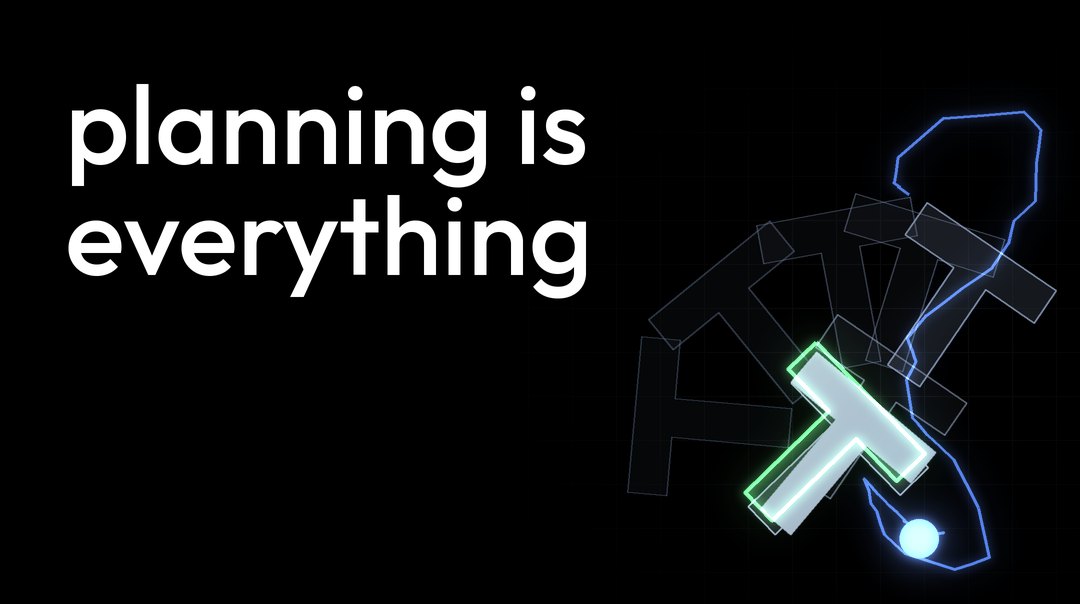
At short horizons of twenty-five steps, LeWM reached targets 89.7 percent of the time, closely trailing the exact physics baseline of 90.5 percent. Compounding errors degrade single long-range predictions, but chaining short searches keeps the planner within its reliable operational envelope. Chaining short hops resolved the compounding error problem far more effectively than physics engines.
Attempting to compensate for long-range degradation through brute-force computation failed during testing. Running the planner four separate times and selecting the lowest-cost plan consumed four times the compute while improving success by less than one percentage point. The repeated searches failed or succeeded together, proving that hierarchical decomposition cannot be replaced by expanded search budgets.
Advertisement
Tech Pulse Daily
Get tomorrow's pulse first
Join engineers who read Tech Pulse before stand-up. Free, weekday mornings.
03Latent memory graphs with penalized transition jumps
Because deployed robots lack human expert demonstrations during live execution, the researcher constructed a topological graph connecting 460,000 embedded observation states. States were linked sequentially within their original trajectories and linked across distinct demonstrations when close in latent space. Embedding distances accurately mirrored physical reachability, ranking reachable subgoals closer than unreachable alternatives 87 percent of the time.
Initial implementations allowed cost-free transitions between separate demonstrations, causing the planner to construct impossible physical paths across disparate trajectories. Out of 1,015 generated plans, 318 attempted to execute six or more jumps that the physical pusher could not execute. Adding an explicit numerical cost to transitions between demonstrations forced the planner to remain on valid physical paths.
Introducing the transition cost penalty elevated task success on the seventy-five-step benchmark from 62 percent to 85 percent. This matched the performance of systems guided by ground-truth expert subgoals while operating entirely autonomously from stored embeddings. The latent graph effectively served as a navigable geometric map without requiring environmental retraining.
04Benchmark stability across two hundred fifty episodes
The standard Push-T benchmark masks planning brittleness because every demonstration terminates with the block resting in the same position. For 84 percent of standard test goals, the memory graph already contained an almost identical state from historical demonstrations. Test goals consistently aligned with pre-existing trajectory streams, creating an artificially favorable evaluation environment.
Sample size limitations further distorted reported performance figures across official evaluation suites. On the official fifty-episode test, LeWM attained a 68 percent success rate at fifty steps, but dropped to 44 percent across two hundred fifty fresh episodes. Merely altering the planner's random seed caused 38 out of 250 test episodes to flip outcomes.
To establish rigorous verification, Alchaer designed a non-overlapping evaluation where starting points and goals were sampled from entirely separate demonstrations. Success required the robotic pusher to maintain target stability during the final ten consecutive steps. Under these stringent rules, standard graph planning scored 75 percent on in-distribution tasks but plunged to 45 percent on cross-demonstration goals.
05Spatial transformations across geometric memory gaps
A memory-based planner degrades rapidly when encountering regions devoid of stored demonstration states. Artificially removing all recorded states adjacent to target positions caused task completion rates to collapse from 93 percent down to 32 percent. The physical environment demands continuous topological coverage to prevent catastrophic navigation failures in sparse regions.
The Push-T physics environment exhibits spatial symmetries that permit data augmentation without additional physical collection. Shifting, rotating, or mirroring the entire table does not alter the underlying mechanics of sliding the T-shaped block. When the memory graph lacks nearby subgoals, transforming distant demonstration segments mathematically fills empty coverage gaps.
Applying geometric transformations to existing memory segments allowed the system to synthesize valid subgoals on the fly. This structural adaptation bridged the performance gap between familiar and out-of-distribution manipulation targets. By exploiting geometric invariants, the architecture solved previously intractable horizons while preserving its zero-retraining footprint.
After 600 experiments FAQ
What is LeWM in robotics research?
LeWM is a joint-embedding predictive architecture world model that uses an encoder, predictor, and planner to evaluate action sequences in latent embedding space rather than generating pixels.
How did chaining subgoals affect long-horizon planning performance?
Breaking seventy-five-step tasks into twenty-five-step subgoals increased task completion rates from 22 percent to 80 percent, overcoming compounding prediction errors without retraining the model.
Why was a jump penalty necessary in the latent memory graph?
Without a transition cost, the planner strung together transitions across different demonstrations that the physical robot could not execute, whereas adding a penalty improved success to 85 percent.
How does benchmark sample size affect Push-T success rates?
Evaluating LeWM over 250 fresh episodes dropped success to 44 percent compared to 68 percent on the official 50-episode test, with 38 outcomes flipping based solely on the planner's random seed.
Sources

Author
Dillip Chowdary
Writes Tech Bytes coverage of AI, engineering, and the tools that actually ship. Editor of Tech Pulse Daily.
Related on Tech Bytes
Advertisement