NVIDIA Unveils Minerva to Bring End-to-End Observability for AI Factories
NVIDIA launched Minerva, an AIOps platform that analyzes billions of hourly telemetry points to detect anomalies across large-scale AI factory GPU clusters.
By Dillip Chowdary • Oct 24, 2026 • Source: NVIDIA Blog
NVIDIA launched Minerva, an AIOps platform to find issues early and optimize AI factory operations, as reported in NVIDIA Blog's report.
This report examines Minerva's architecture, telemetry processing, dynamic knowledge graphs, and server partner availability for engineers managing large GPU clusters.
NVIDIA Minerva to Bring End-to-End: the announcement
Minerva addresses the operational demands of AI factories where massive numbers of GPUs collaborate across high-speed networks to train models and serve AI applications. In these large installations, subtle warning signs like a GPU running hotter than its peers or an NVMe drive losing throughput under load often go unnoticed until jobs stall. Minerva focuses on AI factory yield, evaluating facility performance through GPU hours, computational goodput, cluster uptime, and total token production to ensure high infrastructure output across enterprise operations daily.
Traditional data center monitoring divides visibility into separate departmental views, isolating networking, compute, site reliability, and machine learning operations. Minerva connects these operational signals across NVIDIA GPUs, SuperNICs, switches, network cables, storage systems, and workload schedulers. By gathering diverse telemetry into a centralized operations platform, engineering teams avoid navigating fragmented alert streams. This combined visibility enables operators to trace performance bottlenecks across physical components and running software jobs before major cluster interruptions happen across large distributed computing facilities worldwide and at scale.
What actually changed with NVIDIA Minerva to Bring End-to-End
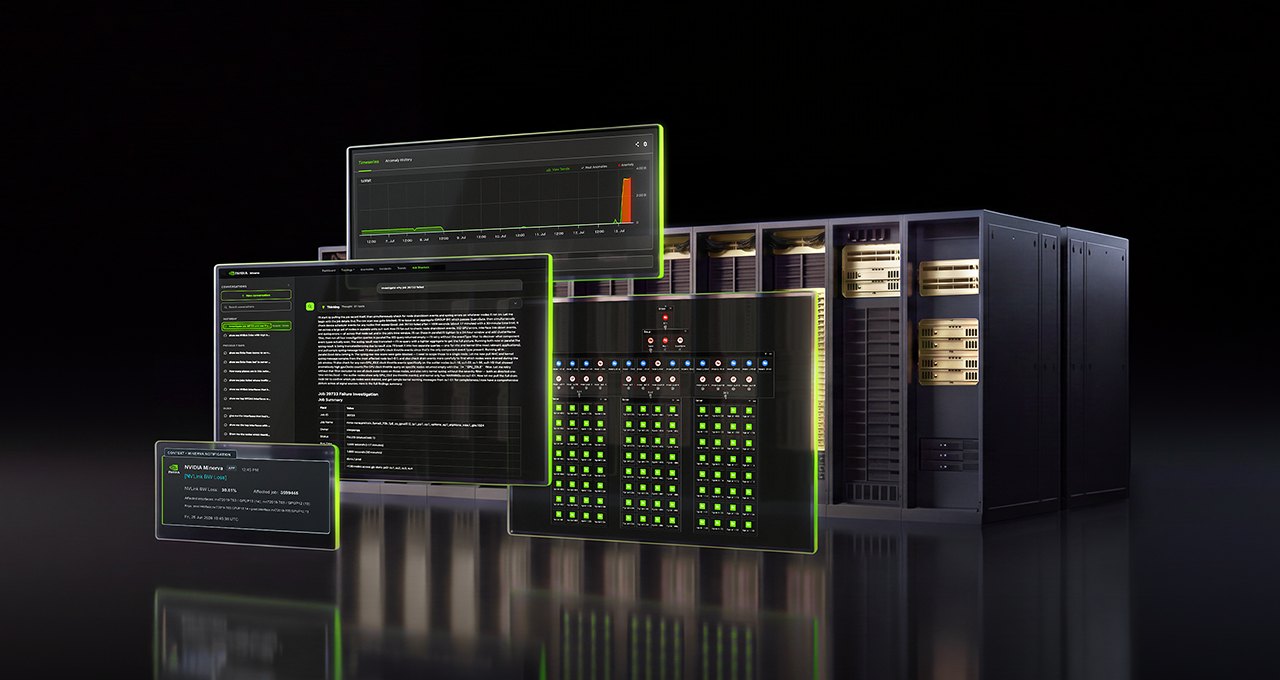
At the foundation of Minerva is a dynamic knowledge graph that logically maps physical infrastructure alongside active compute workloads. The system ingests and analyzes billions of data points per hour using supervised and unsupervised machine learning algorithms. Minerva learns normal operational patterns, detects previously unseen anomalies, forecasts emerging hardware failures, and correlates concurrent events based on data center topology. When component issues arise, the platform groups chaotic symptom storms into an isolated incident accompanied by an identified probable root cause for engineering teams.
Operational workflows change further through a native AI assistant paired with connections to external agentic AI tools. This natural-language interface grounds conversations in live telemetry, enabling operators to examine cluster health and receive remediation recommendations interactively. Engineering teams can keep a person in the loop to apply recommended fixes manually or connect Minerva to infrastructure application programming interfaces and external systems for automated resolution, simplifying operational oversight across large computing clusters containing hundreds of thousands of GPUs during active training jobs.
Advertisement
Tech Pulse Daily
Get tomorrow's pulse first
Join engineers who read Tech Pulse before stand-up. Free, weekday mornings.
Who should care about NVIDIA Minerva to Bring End-to-End
Hyperscale operators, sovereign cloud builders, and enterprise engineering teams managing massive GPU clusters face immediate operational benefits from this platform. Tracing a slow distributed training job to a single failing component across hundreds of thousands of GPUs previously required tedious cross-team investigation. Minerva provides site reliability engineers, network administrators, and machine learning teams with a unified operational view, enabling data center operators to transition away from reactive troubleshooting toward systematic proactive maintenance routines that protect valuable computing resources and project schedules.
Early industry partners emphasize the importance of maximizing processor productivity across large facilities. Denis Skrinnikoff, chief technology officer of cloud infrastructure provider IREN, stated that Minerva provides their operations team with one view across the network, GPUs, and running jobs to focus on proactive maintenance rather than troubleshooting. In addition to IREN, companies planning to deploy Minerva include Aolani, Bitdeer AI, IBM, Jio, Lambda, Quake AI, and Tesla to optimize their accelerated computing operations and maximize cluster uptime across sites.
How to try NVIDIA Minerva to Bring End-to-End
Enterprise organizations planning to implement Minerva can access the software through major server original equipment manufacturers. Hardware partners Dell Technologies, Lenovo, and Supermicro will offer Minerva as part of their AI factory operations portfolios. Enterprise customers building accelerated computing clusters can obtain the platform through these certified server vendors, simplifying the deployment of telemetry ingestion pipelines across specialized GPU nodes, high-performance storage arrays, and high-speed networking switches without having to construct complex custom data harvesting systems from scratch in their facilities.
Deploying Minerva involves connecting cluster telemetry from supported GPUs, SuperNICs, switches, cables, and storage systems into the dynamic knowledge graph engine. Operations teams can query cluster conditions through the conversational AI assistant or integrate the platform with existing management consoles through infrastructure application programming interfaces. Organizations looking to adopt the platform should coordinate directly with system providers Dell Technologies, Lenovo, or Supermicro to evaluate integration roadmaps, hardware requirements, and deployment timelines for their accelerated computing infrastructure installations and cluster rollout phases.
What to watch after NVIDIA Minerva to Bring End-to-End
Following deployment across production clusters, key indicators will center on whether Minerva delivers measurable gains in AI factory yield. Key operational benchmarks include longer intervals between job interruptions, faster time to repair through pinpointed root-cause analysis, and reduced alert fatigue by filtering noise from massive telemetry streams. Observers will track how effectively the platform flags early warnings, such as thermal variances in individual processors or degraded NVMe performance, before active training runs or distributed inference pipelines experience costly slowdowns across high-capacity data centers.
Industry watchers should also monitor the expansion of automated remediation driven by external agentic artificial intelligence tools. While initial deployments maintain human oversight for applying fixes, proven diagnostic accuracy may accelerate the shift toward programmatic API-level corrections. Deployments across major partner installations, including Tesla, IBM, Jio, and Lambda, will indicate how effectively Minerva scales across varied workloads and complex infrastructure topologies supporting global enterprise computing demands and high-throughput model training jobs across modern accelerated facilities worldwide in production environments today.
Developer Action Items
- ☐ Diff the official changelog for Nvidia before you bump — APIs, defaults, and removed flags only.
- ☐ Install through the vendor's documented channel in staging; keep a one-command rollback and time-box the canary.
- ☐ Grep your repo for old flag names, lockfile pins, and plugin versions that the notes mark as breaking.
- ☐ Prefer the first patch cut over the day-zero tag unless you have a reason to be on the leading edge.
- ☐ If NVIDIA Blog did not name a region, plan, or SKU, screenshot the official availability line before you promise it to users.
NVIDIA Minerva to Bring End-to-End FAQ
What is NVIDIA Minerva?
An AIOps platform unifying telemetry across infrastructure and workloads to optimize AI factory yield.
Who plans to deploy Minerva?
Partners include IREN, Aolani, Bitdeer AI, IBM, Jio, Lambda, Quake AI, and Tesla.
Which hardware partners offer Minerva?
Dell Technologies, Lenovo, and Supermicro will offer Minerva in their operations portfolios.
Sources

Author
Dillip Chowdary
Writes Tech Bytes coverage of AI, engineering, and the tools that actually ship. Editor of Tech Pulse Daily.
Related on Tech Bytes
Advertisement