Uber Cuts Translation Cache Memory by up to 90% While Keeping P99 Latency
Uber redesigned its Go translation cache to cut initial memory by over 90 percent while maintaining sub-millisecond p99 miss latency and a 99.9% hit rate.
In short
Go backend engineers and platform architects · Over 90% memory cut and <100µs p99 miss latency · In production across Uber Go services · Store keys in RAM and stream idle values from disk
By Dillip Chowdary • Nov 21, 2026 • Source: InfoQ
At a glance
- Who it is for
- Go backend engineers and platform architects
- The number
- Over 90% memory cut and <100µs p99 miss latency
- Available
- In production across Uber Go services
- What to do
- Store keys in RAM and stream idle values from disk
- Publish date
- November 20, 2026
- Shard limit
- 256 shards with 50,000 cached entries
Uber redesigned its Go-based translation cache to cut initial memory consumption by more than 90 percent while serving millions of translations per second and keeping p99 cache miss latency under one millisecond, according to InfoQ's report.
This architectural breakdown is designed for backend engineers maintaining Go microservices burdened by heavy heap allocations and frequent garbage collection cycles. Engineering teams can apply these principles by keeping active cache keys in memory while offloading infrequently accessed dataset values to local disk storage.
01Garbage collection overhead across services
Internal memory profiling across Uber's Go services uncovered severe runtime inefficiencies caused by translation caching. Garbage collection routines consumed more than 20 percent of CPU utilization in several production microservices, drawing system resources away from primary request processing. Investigations confirmed that translation datasets were responsible for approximately 70 percent of all allocated objects inside the affected runtimes.
Uber Engineering noted that even minor inefficiencies in memory management aggregate rapidly at enterprise scale. Because their infrastructure serves millions of translation lookups every second, retaining massive object graphs in heap memory magnified runtime penalties across host clusters. The constant pointer traversals during garbage collection sweeps created latency variability that degraded fleet-wide service performance.
Engineers determined that traditional caching strategies failed to account for object lifecycle dynamics in high-throughput environments. The sheer volume of live references forced the Go runtime to scan millions of heap allocations during every garbage collection cycle. Resolving the issue required rethinking how translation strings were stored, indexed, and dereferenced inside service memory.
02Value map migration and memory limits
The initial optimization targeted synchronization structures inside the existing cache layer. Uber initially deployed Go's sync.Map to coordinate concurrent translation access across service worker threads. Because the production workload was overwhelmingly read-heavy with rare updates and zero individual entry deletions, sync.Map generated unnecessary pointer indirections and multiple heap object allocations for every translation item.
To eliminate those allocations, developers replaced sync.Map with a conventional Go map structure keyed by strings to string values, guarded by a read-write mutex. This direct value-based map reduced pointer overhead and eliminated redundant heap objects, delivering an immediate CPU utilization improvement of over 30 percent. However, the architectural switch did not solve overall memory exhaustion across clusters.
Note: Translation datasets contained two to three million keys, but individual services accessed only a small fraction. Periodic cache refreshes compiled complete replacement datasets in the background before executing atomic pointer swaps, which temporarily doubled heap consumption and caused microservices to crash from out-of-memory errors.
03Sharded disk storage and hash keys
Advertisement
Tech Pulse Daily
Get tomorrow's pulse first
Join engineers who read Tech Pulse before stand-up. Free, weekday mornings.
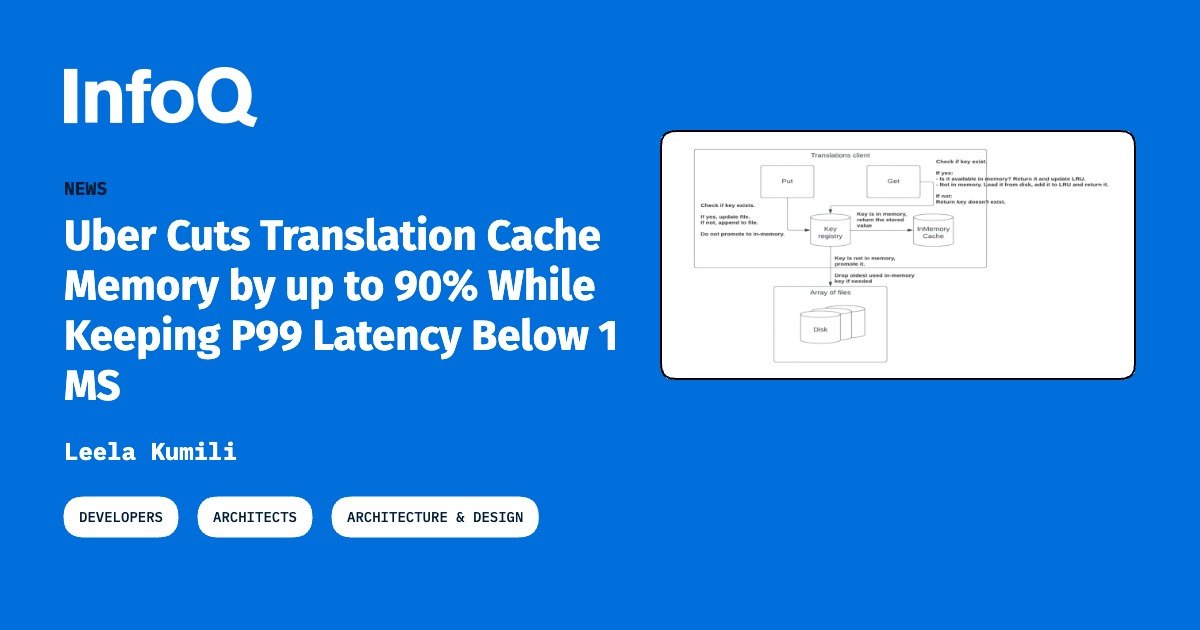
Uber reviewed external caching tiers and service-specific dataset generation before dismissing both approaches due to prohibitive operational overhead and maintenance costs. Instead, engineers developed a hybrid storage architecture that maintained full backward compatibility with the existing Get() and Put() API. All lookup keys remain resident in memory for instant verification, while actual translated text values reside on disk.
The storage engine distributes translation entries across 256 individual shards, each containing an independent read-write mutex, in-memory index, and dedicated disk file. To minimize metadata overhead, the cache maps entries using compact six-byte hash keys while retaining original string keys as an automated fallback to resolve potential hash collisions. A global time-based least recently used eviction policy regulates memory occupancy.
Partitioning data across 256 shards prevents lock contention across concurrent read threads during peak traffic intervals. Each shard manages its file handles independently, ensuring that disk access routines operate without blocking unrelated translation lookups. By isolating concurrency boundaries to individual shards, the system achieves predictable throughput while holding memory usage within strict administrative boundaries.
04Memory footprint reductions and latency benchmarks
Production benchmarks verified dramatic resource savings across multiple production workloads without sacrificing response speed. In one documented dataset, translations that previously consumed 800 MB of heap memory required only 40 MB for key metadata after migrating to the hybrid model. When configured with a ceiling of 50,000 in-memory items, actual runtime memory hovered between 80 MB and 120 MB.
In a larger production service managing more than four million entries, the hybrid cache loaded approximately 30,000 active translations into RAM while sustaining a cache hit rate above 99.9 percent. The p99 retrieval latency for disk-backed cache misses remained below 100 microseconds, easily surpassing the operational requirement of sub-millisecond retrieval. Overall service memory plummeted from 2.7 GB to 750 MB.
The transition to a hybrid caching model delivered measurable improvements across CPU utilization, heap retention, and retrieval latencies across production environments. Fleet telemetry confirmed that total service memory consumption dropped from approximately 2.7 GB down to 750 MB while preserving sub-millisecond retrieval thresholds across all production clusters.
| Metric | Previous in-memory cache | Redesigned hybrid cache |
|---|---|---|
| Initial dataset memory | ~800 MB | 80 MB–120 MB |
| Index metadata size | Unoptimized pointers | ~40 MB (6-byte hash keys) |
| Full service memory | ~2.7 GB | ~750 MB |
| Garbage collection overhead | >20% CPU utilization | >30% CPU improvement |
| Cache hit rate | Not reported | >99.9% |
| P99 cache miss latency | Not reported | <100 microseconds (<1 ms) |
05Cache preloading and production recommendations
Traditional cache swaps frequently introduce cold-cache penalties that degrade system latency immediately following deployment. To eliminate performance dips during dataset refreshes, Uber's system inspects access history logs and preloads translations queried within the preceding 15 minutes directly into memory. This targeted warming routine ensures that frequently accessed strings remain available in RAM before the atomic pointer swap activates.
Uber Engineering recommends that platform developers actively profile object references to mitigate garbage collection overhead in memory-intensive microservices. Teams should evaluate how frequently cached values are accessed in production rather than assuming all entries justify permanent heap residency. When applications read only a narrow subset of keys, migrating inactive values to disk achieves massive efficiency gains.
Engineers designing high-throughput Go services can apply these lessons to reduce infrastructure costs and stabilize tail latencies. Combining compact hash-based indexing with sharded local disk storage allows services to scale datasets to millions of entries without inflating heap allocations. Measuring object allocation profiles remains the most reliable path toward identifying hidden garbage collection bottlenecks.
Frequently asked questions
How much memory did Uber save by redesigning its translation cache?
The hybrid architecture reduced initial memory consumption by more than 90 percent, dropping heap usage in one workload from 800 MB to between 80 MB and 120 MB. In another production service, overall memory footprint fell from 2.7 GB to 750 MB.
How did Uber achieve sub-millisecond cache miss latency with disk storage?
Uber partitioned the cache into 256 shards, each with its own read-write mutex and disk file, while indexing entries with six-byte hash keys. This architecture kept p99 disk-backed cache miss latency below 100 microseconds while maintaining a cache hit rate above 99.9 percent.
Why did Uber replace Go's sync.Map in its initial optimization?
Uber's translation workload was read-heavy with infrequent updates and zero individual deletions. Replacing sync.Map with a standard map[string]string protected by an RWMutex eliminated unnecessary pointers and object allocations, improving CPU utilization by over 30 percent.
How does the hybrid translation cache prevent cold-cache latency spikes during refreshes?
During background cache refreshes, the system reviews access history logs and preloads all translations requested within the prior 15 minutes into memory. This ensures active keys and values are hot in RAM before the atomic pointer swap occurs.
Sources

Author
Dillip Chowdary
Writes Tech Bytes coverage of AI, engineering, and the tools that actually ship. Editor of Tech Pulse Daily.
Related on Tech Bytes
Advertisement