Article: Systemic Approach to Memory, Knowledge, and Context in Agentic AI
InfoQ published an architectural guide detailing why autonomous AI agents require dedicated context engines to fuse historical memory with real-time telemetry.
By Dillip Chowdary • Nov 02, 2026 • Source: InfoQ
Software architecture for autonomous artificial intelligence is transitioning from prompt crafting to dedicated context control planes, according to InfoQ's report by Adi Polak, reviewed by Rafał Gancarz on November 2, 2026. As teams shift from chatbots to autonomous agents, the bottleneck moves from simple data retrieval to deciding what an agent knows, when it accesses data, and what it forgets before calling model inference endpoints.
This analysis details the architectural separation of context, memory, and knowledge required to curb model hallucinations and control compute costs in agentic systems. The breakdown addresses software architects and platform engineers who must reconcile long-term historical records with streaming real-time telemetry. By treating the context engine as an authenticating compiler rather than a prompt template, developers can construct reliable deterministic state machines around probabilistic language models.
Systemic Approach to Memory: what actually changed
The primary evolution in agentic software engineering replaces manual prompt design with a deterministic context control plane that governs model inputs at the millisecond level. Traditional agent workflows relied on prompt engineering to craft instructions, assuming better phrasing would ensure reliable model outputs. Under the systemic architecture outlined by Polak and Gancarz, engineering teams decouple the underlying language model from its surrounding data machinery. The context engine acts as a centralized control plane, pulling records from foundational knowledge bases and routing them through memory layers to compile minimal, high-value prompts before executing an inference request.
This framework formally divides data assets into three distinct architectural tiers: context, memory, and knowledge. Context serves as the immediate, temporary working memory sitting directly inside the active context window, behaving like physical computer RAM during execution. Memory supplies state persistence across separate user sessions, enabling the agent to retain past decisions, learn from historical interactions, and modify behavior over time. Knowledge acts as the system official textbook, storing immutable domain logic, hard corporate policies, and curated reference databases. Keeping these layers separated prevents agents from conflating background enterprise truth with ephemeral session inputs or obsolete interaction logs.
Systemic Approach to Memory: how it works
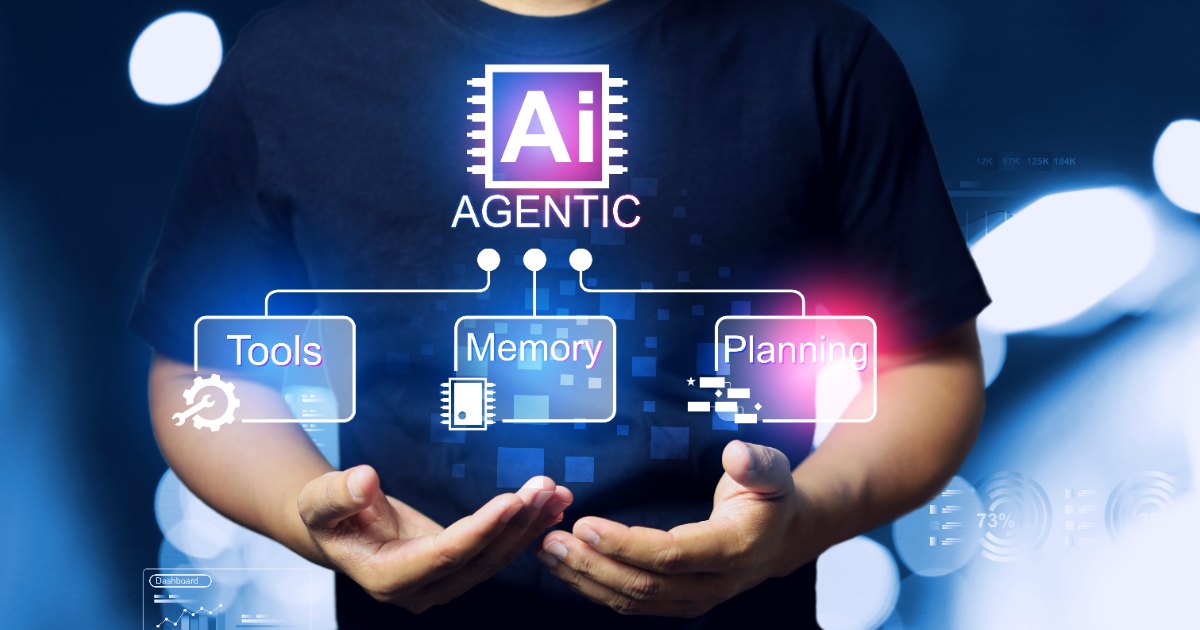
The context engine operates like a software compiler, converting unstructured historical data and live telemetry into structured, reasoning-ready states. In a standard workflow, the engine ingests raw inputs, validates them against business policies, authenticates callers, strips personally identifiable information, and isolates external tools inside secure execution sandboxes. Instead of flooding an LLM with unbounded background information, the engine enforces token budgeting by ranking, filtering, and compressing data before dispatch. The resulting structured payload establishes a deterministic state machine that constrains probabilistic outputs, curbing hallucinations caused by malformed, noisy, or irrelevant context.
To illustrate this selective filtering mechanism, the architecture uses the analogy of preparing an omelet. A cook operating with proper knowledge understands the fundamental requirement for eggs and a frying pan, but the immediate task context does not require remembering techniques for kneading dough. The context engine mirrors this behavior by dynamically determining what facts belong in working memory for the active assignment. It synchronizes long-term historical records with streaming telemetry so the model remains strictly focused on current operational boundaries rather than processing irrelevant enterprise background rules during an execution step.
Advertisement
Tech Pulse Daily
Get tomorrow's pulse first
Join engineers who read Tech Pulse before stand-up. Free, weekday mornings.
Systemic Approach to Memory: why it matters now
Balancing historical and real-time state has emerged as the defining engineering hurdle for autonomous enterprise deployments. Historical episodic memory captures accumulated user preferences, past architectural choices, and corporate documentation, granting the autonomous system behavioral continuity. Conversely, real-time sensory memory ingests the latest operational signals, tool outputs, and live system events. If an agent over-indexes on historical context, it becomes functionally stale and misapplies yesterday assumptions to fresh operational crises. Conversely, over-indexing on immediate sensory signals produces a hyper-reactive, forgetful agent that responds to momentary noise while losing strategic context.
Real-world production environments expose the practical danger of uncoordinated memory streams. Consider an automated DevOps agent tasked with triaging an active cloud infrastructure outage. Retrieving an incident runbook from a historical vector database provides semantic background, but that documentation accounts for only half of the triage workflow. The agent simultaneously requires the live error log stream generated across the preceding five seconds to diagnose the active failure. The context engine fuses these asynchronous batch and streaming feeds into a unified view, allowing the agent to evaluate real-time telemetry against verified historical baselines.
Systemic Approach to Memory: who is affected
Software architects and engineering leads building autonomous agent workflows across enterprise environments are directly impacted by this architectural realignment. Teams that previously relied on naive vector database retrieval and monolithic prompt strings must restructure their backends around dedicated context pipelines. This transition forces developers to implement strict token budgeting and automated data expiration policies to rein in inference latency and cloud compute expenditures. Without an orchestrating control plane to select and sanitize injected data, organizations deploying production agents face escalating operational costs and unpredictable model reasoning failures caused by uncurated, bloated context windows.
Platform engineers managing governance, compliance, and enterprise data privacy must also adjust their integration patterns. Because the context engine serves as the mandatory gatekeeper between corporate datastores and external model endpoints, security teams must embed authentication checks and automated personally identifiable information redaction directly into the compilation layer. This shifts data protection from post-generation output filters to the pre-inference assembly stage. Development teams preparing for production deployments must treat context curation as an essential system requirement rather than an optional optimization applied after prototyping.
Systemic Approach to Memory: what to watch
Industry adoption of dedicated context engines will accelerate as software organizations transition experimental prototypes into resilient production systems. A critical milestone on this trajectory is QCon AI Boston, scheduled for July 8-9, 2027, where technical leaders will address the operational challenges that emerge when moving generative prototypes into live production environments. Watch for enterprise framework developers to publish standardized context compiler tooling that bundles token compression algorithms, automated session expiry, and streaming telemetry connectors into unified runtime libraries, replacing fragile ad-hoc prompt templates.
Engineering teams should also monitor how emerging agent standards formalize the boundary between immutable knowledge repositories and mutable memory stores. As vector stores evolve beyond static similarity search, integration patterns will increasingly emphasize sub-second synchronization between live sensory streams and episodic archives. Organizations that master selective context injection will significantly reduce inference overhead while mitigating the hallucinations that plague raw prompt pipelines. The transition from manual prompt design to automated context compilation marks the maturation of agentic software architecture into a rigorous engineering discipline.
Developer Action Items
- ☐ Verify the claim on the official Framework page (or InfoQ), not from this recap alone.
- ☐ Name the surface that moved — API, policy, model, hardware, or commercial terms — before you Slack the thread.
- ☐ Assign one owner a day to read the primary material and decide: this-sprint, this-quarter, or noise.
- ☐ Do not change production on day-one coverage. Watch the vendor changelog and one independent write-up first.
Systemic Approach to Memory FAQ
What is the difference between context, memory, and knowledge in agentic AI?
Context is the active, temporary data held in the model working window, functioning like computer RAM during a task. Memory provides persistence across interactions to learn from past decisions, while knowledge acts as the curated textbook containing foundational business rules and reference facts.
Why do vector databases alone fail to solve agentic memory needs?
Vector stores retrieve long-term episodic facts, but production agents also require immediate sensory data, such as error logs from the last five seconds during an outage. An effective context engine must asynchronously fuse both historical retrieval and real-time streaming signals to prevent stale reasoning.
How does a context engine function as a compiler?
A context engine translates raw, unstructured historical and live data into a structured, reasoning-ready state before reaching the model endpoint. It authenticates inputs, strips personally identifiable information, validates business logic, and sandboxes tools to build a deterministic state machine around the probabilistic agent.
What causes hallucinations in production AI agents according to the architecture?
Hallucinations frequently stem from context failures rather than model flaws, specifically when systems inject malformed, irrelevant, or excessive data into the prompt. Structuring, ranking, and compressing context to provide small, relevant inputs significantly improves reasoning accuracy.
Sources

Author
Dillip Chowdary
Writes Tech Bytes coverage of AI, engineering, and the tools that actually ship. Editor of Tech Pulse Daily.
Related on Tech Bytes
Advertisement